A Screaming Frog SEO audit is the fastest way to find out what search engines actually see when they crawl your site, as opposed to what your CMS believes it is publishing. The tool crawls your URLs the way a bot does and hands you the raw evidence: which pages cannot be indexed, which redirect twice before resolving, which share the same title, which return a 404 from a link in your own navigation.
This guide walks the checks in the order they are worth running, and explains what to do with each finding rather than just where the tab is.
Before you start: what the free version gives you
A widely repeated claim online is that the free SEO Spider crawls up to 50,000 URLs. It does not. The free version is limited to 500 URLs per crawl, which is enough for a small brochure site and nowhere near enough for an e-commerce catalog. The licence is £199 a year and removes the limit.
The free version also excludes several things you will want the moment the audit gets serious: JavaScript rendering, the Google Search Console, Analytics and PageSpeed Insights API integrations, structured data validation, crawl comparison, scheduling and saved crawls. If you are auditing a client site once, the free tier will show you the shape of the problem. If you are auditing regularly, the licence pays for itself in the first engagement.
Setting up the Screaming Frog SEO audit
Enter the domain and click Start. On a small site the crawl finishes in minutes; on a large one, plan for it and let it run.
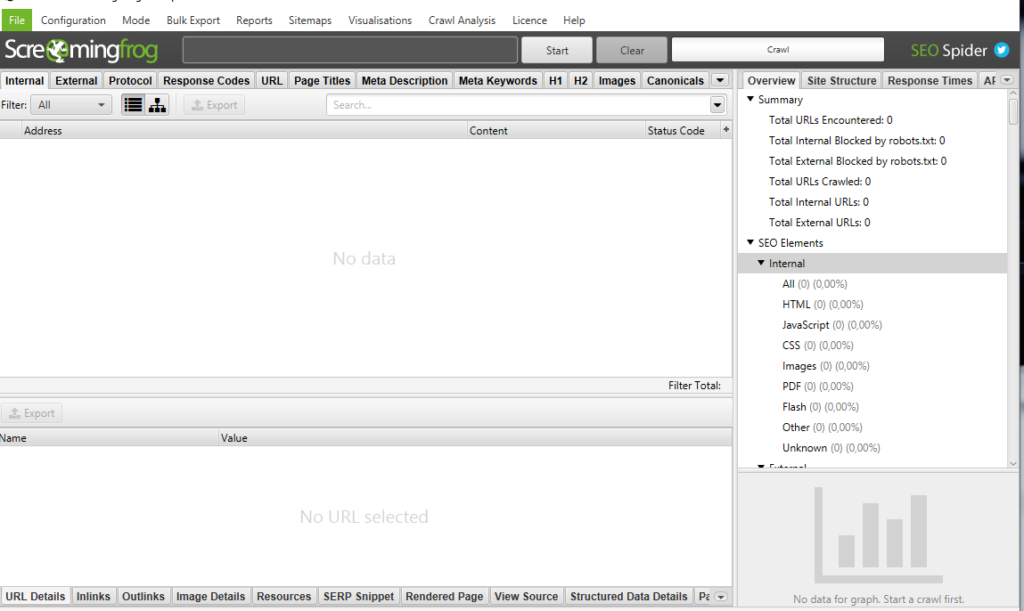
Three settings are worth checking before you press Start, because getting them wrong invalidates the whole crawl:
- Rendering. If the site is built on React, Vue or a headless setup, switch rendering to JavaScript. Crawl it in the default HTML mode and you will see an almost empty site and conclude, wrongly, that nothing is indexable.
- User agent and robots.txt. By default the crawler respects robots.txt. Keep it that way for the first pass — you want to see the site as Googlebot sees it — then run a second, ignoring robots.txt, to find out what you are blocking.
- API connections. With a licence, connect Search Console, GA4 and PageSpeed Insights before crawling. This is the difference between a list of technical faults and a prioritized one, because you can then sort broken pages by the traffic they actually receive.
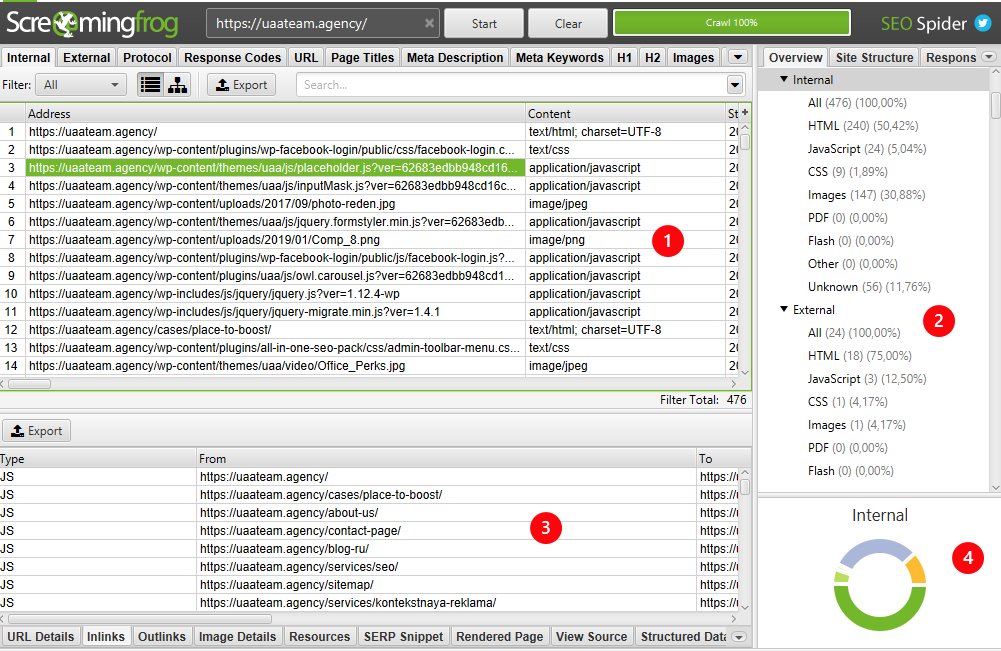
The window splits into four areas: the URL table, the overview panel with counts and percentages, the detail pane for whichever URL you select, and the site structure diagram. Most of the audit happens by picking a filter in the overview panel and reading the resulting list.
1. Indexability
The Indexability column tells you whether a URL can appear in search results, and the Indexability Status column tells you why not — noindex, canonicalised elsewhere, blocked by robots.txt, redirected.
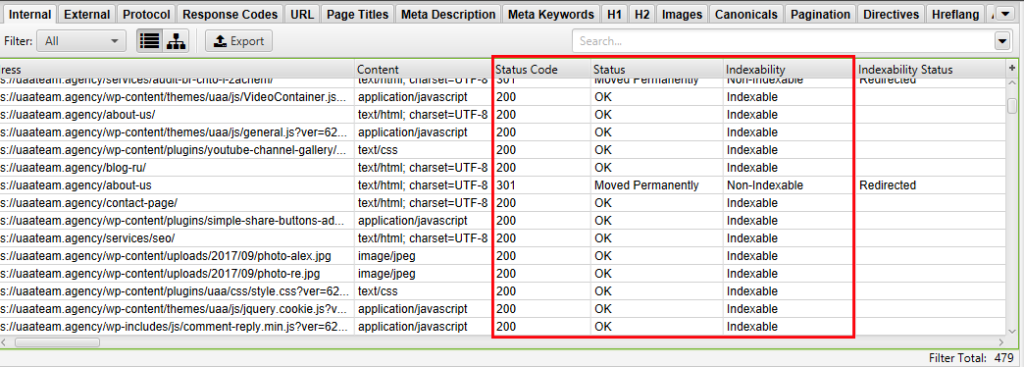
Every Screaming Frog SEO audit should start here, and with the pages that make you money: category pages, product pages, service pages. A non-indexable money page is the most expensive bug this tool finds, and it is usually a staging noindex that was never removed or a robots.txt rule written for a directory structure that has since changed.
Non-indexable is not automatically wrong. Faceted filter URLs, internal search results and paginated duplicates should be excluded. What you are looking for is the gap between what you intended to exclude and what is actually excluded.
2. Response codes
Every URL should return the code that matches its purpose: 200 for live pages, 301 for permanently moved ones, 302 only for genuinely temporary moves, 404 for pages that are gone and should stay gone.
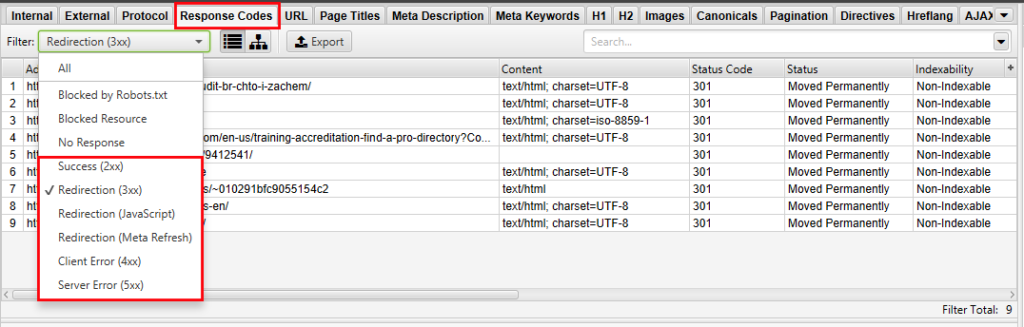
Three findings matter more than the raw counts:
- Internal links pointing at redirects. A 301 is fine as a destination for an old external link. It is waste when your own navigation links to it. Use the Redirect Chains report, then fix the links at source so they point at the final URL.
- Redirect chains and loops. Two hops is sloppy; three or more starts costing you crawl budget and load time. A loop is a dead page.
- 404s with inlinks. A 404 nobody links to is harmless. A 404 linked from your own category page is a broken user journey. Sort by inlinks, not by count.
A common misconception worth dropping: chasing “100% of pages returning 200” is not a goal. A correct 404 is a correct answer.
3. Titles and meta descriptions
The overview panel gives you the counts — missing, duplicate, over length, below length — and clicking a filter gives you the list.
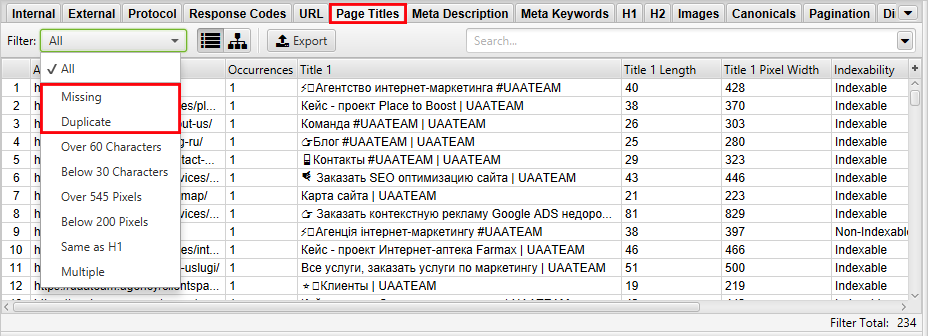
Duplicates are the finding that pays. On most e-commerce sites they come from a template that generates the same title for every page in a category, or from a paginated series where page 2 through page 40 all claim to be page 1. Fix the template and you fix hundreds of URLs at once, which is a far better use of a day than rewriting titles individually.
Treat the length warnings as advisory. Google rewrites titles frequently, and a title that is three characters over the pixel limit is not the reason a page does not rank.
4. H1 tags
Check two things: that every important page has one, and that it has only one. Multiple H1s in the body are common on sites where the theme already outputs the post title as an H1 and the editor adds another inside the content.
5. Images
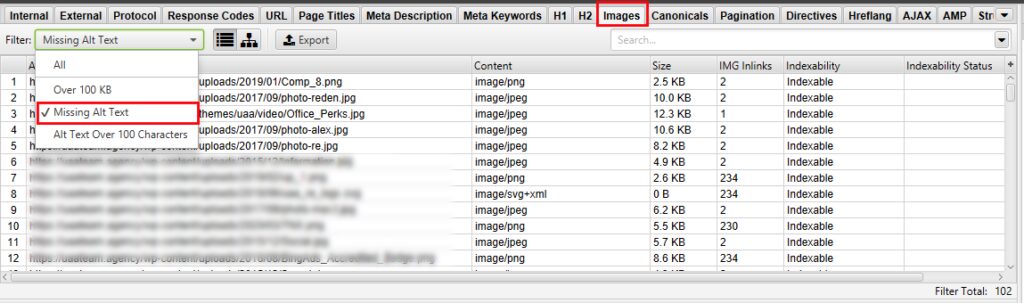
The Images tab flags missing alt text and oversized files. Alt text matters for accessibility and for image search; on a product catalog it is often the single largest batch of quick wins, because the fix is a template change rather than manual work.
On file size, ignore fixed thresholds like “nothing over 100 KB” and look at what is actually hurting you. The image that matters is the one in the largest contentful paint — usually the hero or the first product shot. A 400 KB image below the fold costs far less than a 200 KB one at the top of the page. Connect the PageSpeed Insights API and let real field data tell you which pages to fix.
6. Canonicals
Canonical tags are where well-meaning setups go wrong quietly. The patterns to look for:
- Pages canonicalising to a URL that redirects, or to a 404.
- Whole sections canonicalising to the homepage — a plugin default that removes those pages from search entirely.
- Canonical pointing at http when the site runs on https, or at the non-www host.
- Paginated series canonicalising every page to page one, which hides deep products from Google.
7. robots.txt and the XML sitemap
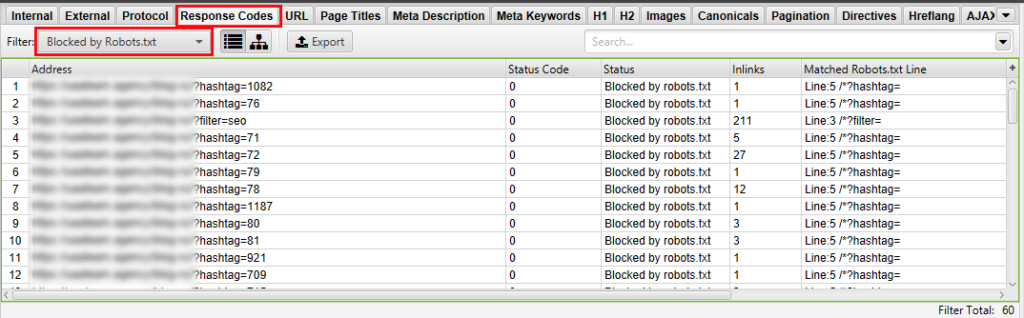
Check that nothing important is blocked, and remember that robots.txt does not remove a page from the index — it only stops the crawl. A page blocked in robots.txt but linked from elsewhere can still appear in results, with no description, which is the worst of both outcomes. Use noindex for removal and robots.txt for crawl control.
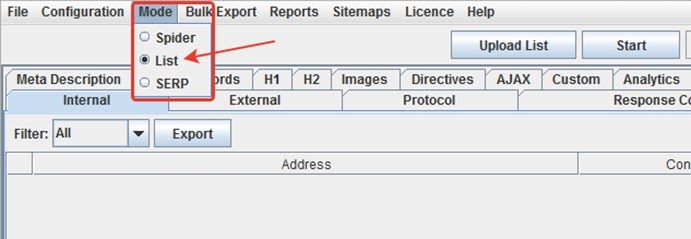
For the sitemap, switch to List mode and feed it your sitemap URL directly. You are looking for URLs in the sitemap that should not be there: redirects, 404s, noindexed pages, canonicalised duplicates. A sitemap full of those tells Google your sitemap is unreliable.
Beyond the basics
Once the standard checks are clean, the licence-only features are where the audit stops being a checklist and starts being diagnostic:
- Structured data validation — crawl-wide checking of your Product, Article, FAQ and Breadcrumb markup, which is far faster than testing URLs one at a time in Google’s rich results tool.
- Crawl comparison — run before and after a migration or a template change and see exactly what moved. This is the single most useful feature during a replatform.
- Custom extraction — pull any element from the page with XPath or CSS selectors: price, stock status, review count, hreflang, a tracking script you need to confirm is present on every page.
- Scheduling — a weekly crawl that emails the report turns the audit from a project into a monitor, so a template change that noindexes a section gets caught in days rather than at the next quarterly review.
Turning a Screaming Frog SEO audit into a plan
The trap with any crawler is exporting eleven thousand rows and calling it an audit. A crawl is evidence, not a plan. What turns it into one:
- Sort every issue list by the page’s Search Console clicks or GA4 sessions, not by issue type. Ten broken canonicals on pages nobody visits are a footnote.
- Group by cause, not by URL. Four hundred duplicate titles are usually one template bug.
- Separate what blocks indexing from what merely looks untidy, and fix the first group before touching the second.
Where to go next
Two checks pair naturally with a crawl. Response codes make more sense once you know what each HTTP status code means for SEO. And a crawl tells you what is on the site, while Search Console tells you what Google did with it — the two together are the whole picture, which is why our SEO audit service runs them side by side.
If the crawl has surfaced more than your team can work through, our SEO team takes the export, groups it by root cause and turns it into a prioritized backlog with the template fixes first.
 223|
 0